Neural Architecture Search, an automated approach at determining the ideal neural network settings can be a plus when facing many options and large test data sets. We examine how when paired Eigen Vectors this process can be made even more efficient.
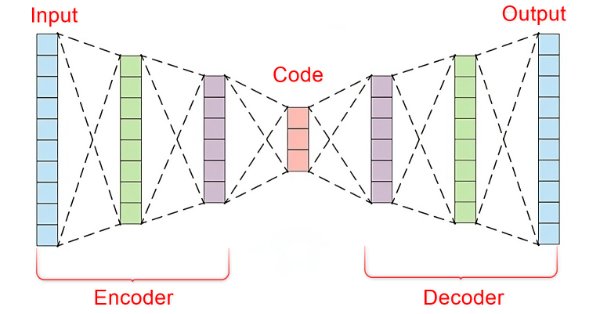
In the fast-paced world of financial markets, separating meaningful signals from the noise is crucial for successful trading. By employing sophisticated neural network architectures, autoencoders excel at uncovering hidden patterns within market data, transforming noisy input into actionable insights. In this article, we explore how autoencoders are revolutionizing trading practices, offering traders a powerful tool to enhance decision-making and gain a competitive edge in today's dynamic markets.
In this article we continue our exploration of the Group Method of Data Handling family of algorithms, with the implementation of the Combinatorial Algorithm along with its refined incarnation, the Combinatorial Selective Algorithm in MQL5.
Since the first articles devoted to reinforcement learning, we have in one way or another touched upon 2 problems: exploring the environment and determining the reward function. Recent articles have been devoted to the problem of exploration in offline learning. In this article, I would like to introduce you to an algorithm whose authors completely eliminated the reward function.
The article considers an optimization method based on the principles of the body's immune system - Micro Artificial Immune System (Micro-AIS) - a modification of AIS. Micro-AIS uses a simpler model of the immune system and simple immune information processing operations. The article also discusses the advantages and disadvantages of Micro-AIS compared to conventional AIS.
The article presents a new approach to solving optimization problems by combining ideas from bacterial foraging optimization (BFO) algorithms and techniques used in the genetic algorithm (GA) into a hybrid BFO-GA algorithm. It uses bacterial swarming to globally search for an optimal solution and genetic operators to refine local optima. Unlike the original BFO, bacteria can now mutate and inherit genes.
In this article we will talk about the importance of APIs (Application Programming Interface) for interaction between different applications and software systems. We will see the role of APIs in simplifying interactions between applications, allowing them to efficiently share data and functionality.
The article considers a group of optimization algorithms known as Evolution Strategies (ES). They are among the very first population algorithms to use evolutionary principles for finding optimal solutions. We will implement changes to the conventional ES variants and revise the test function and test stand methodology for the algorithms.
ONNX is a great tool for integrating complex AI code between different platforms, it is a great tool that comes with some challenges that one must address to get the most out of it, In this article we discuss the common issues you might face and how to mitigate them.
Principal Component Analysis, a dimensionality reducing technique in data analysis, is looked at in this article, with how it could be implemented with Eigen values and vectors. As always, we aim to develop a prototype expert-signal-class usable in the MQL5 wizard.
The article examines the impact of changing the shape of probability distributions on the performance of optimization algorithms. We will conduct experiments using the Smart Cephalopod (SC) test algorithm to evaluate the efficiency of various probability distributions in the context of optimization problems.
The first part was devoted to the well-known and popular algorithm - simulated annealing. We have thoroughly considered its pros and cons. The second part of the article is devoted to the radical transformation of the algorithm, which turns it into a new optimization algorithm - Simulated Isotropic Annealing (SIA).
The Simulated Annealing algorithm is a metaheuristic inspired by the metal annealing process. In the article, we will conduct a thorough analysis of the algorithm and debunk a number of common beliefs and myths surrounding this widely known optimization method. The second part of the article will consider the custom Simulated Isotropic Annealing (SIA) algorithm.
Support Vector Machines classify data based on predefined classes by exploring the effects of increasing its dimensionality. It is a supervised learning method that is fairly complex given its potential to deal with multi-dimensioned data. For this article we consider how it’s very basic implementation of 2-dimensioned data can be done more efficiently with Newton’s Polynomial when classifying price-action.
In this article, we continue discussing methods for collecting data into a training set. Obviously, the learning process requires constant interaction with the environment. However, situations can be different.
Models are trained offline using data from a prepared training dataset. While providing certain advantages, its negative side is that information about the environment is greatly compressed to the size of the training dataset. Which, in turn, limits the possibilities of exploration. In this article, we will consider a method that enables the filling of a training dataset with the most diverse data possible.
Embark on the next phase of our MQL5 journey. In this insightful and beginner-friendly article, we'll look into the remaining array functions, demystifying complex concepts to empower you to craft efficient trading strategies. We’ll be discussing ArrayPrint, ArrayInsert, ArraySize, ArrayRange, ArrarRemove, ArraySwap, ArrayReverse, and ArraySort. Elevate your algorithmic trading expertise with these essential array functions. Join us on the path to MQL5 mastery!
The article presents a complete exploration of the Nelder-Mead method, explaining how the simplex (function parameter space) is modified and rearranged at each iteration to achieve an optimal solution, and describes how the method can be improved.
In this article, we will consider the algorithm that demonstrates the most controversial results of all those discussed previously - the differential evolution (DE) algorithm.
In this article, we will create a random forest model in Python, train the model, and save it as an ONNX pipeline with data preprocessing. After that we will use the model in the MetaTrader 5 terminal.
In this article, we will get acquainted with an interesting algorithm that is built at the intersection of supervised and reinforcement learning methods.
Spatial Temporal Fusion which is using both ‘space’ and time metrics in modelling data is primarily useful in remote-sensing, and a host of other visual based activities in gaining a better understanding of our surroundings. Thanks to a published paper, we take a novel approach in using it by examining its potential to traders.
The article presents an optimization algorithm based on the patterns of constructing spiral trajectories in nature, such as mollusk shells - the spiral dynamics optimization (SDO) algorithm. I have thoroughly revised and modified the algorithm proposed by the authors. The article will consider the necessity of these changes.
Dive into the heart of neural networks as we demystify the optimization algorithms used inside the neural network. In this article, discover the key techniques that unlock the full potential of neural networks, propelling your models to new heights of accuracy and efficiency.
Can we benefit from seasonality when creating models for Deep Learning with Python? Does filtering data for the ONNX models help to get better results? What time period should we use? We will cover all of this over this article.
The article considers an interesting algorithm derived from inanimate nature - intelligent water drops (IWD) simulating the process of river bed formation. The ideas of this algorithm made it possible to significantly improve the previous leader of the rating - SDS. As usual, the new leader (modified SDSm) can be found in the attachment.
As a result of tests performed in previous articles, we came to the conclusion that the optimality of the trained strategy largely depends on the training set used. In this article, we will get acquainted with a fairly simple yet effective method for selecting trajectories to train models.
Density Based Spatial Clustering for Applications with Noise is an unsupervised form of grouping data that hardly requires any input parameters, save for just 2, which when compared to other approaches like k-means, is a boon. We delve into how this could be constructive for testing and eventually trading with Wizard assembled Expert Advisers
We continue to discuss the family of Decision Transformer methods. From previous article, we have already noticed that training the transformer underlying the architecture of these methods is a rather complex task and requires a large labeled dataset for training. In this article we will look at an algorithm for using unlabeled trajectories for preliminary model training.
Explore the world of MQL5 arrays in Part 5, designed for absolute beginners. Simplifying complex coding concepts, this article focuses on clarity and inclusivity. Join our community of learners, where questions are embraced, and knowledge is shared!
The article considers the practical application of quantization in the construction of tree models. The methods for selecting quantum tables and data preprocessing are considered. No complex mathematical equations are used.
In recent articles, we have seen several options for using the Decision Transformer method. The method allows analyzing not only the current state, but also the trajectory of previous states and actions performed in them. In this article, we will focus on using this method in hierarchical models.
In this article, we explore the challenge of understanding how AI works. AI models often make decisions in ways that are hard to explain, leading to what's known as the "disagreement problem". This issue is key to making AI more transparent and trustworthy.
In this article, we will consider another optimization algorithm inspired by inanimate nature - Charged System Search (CSS) algorithm. The purpose of this article is to present a new optimization algorithm based on the principles of physics and mechanics.
We will guide you through the entire process of DL with python to make a GRU ONNX model, culminating in the creation of an Expert Advisor (EA) designed for trading, and subsequently comparing GRU model with LSTM model.
This article describes the implementation of a regression model based on a decision tree. The model should predict prices of financial assets. We have already prepared the data, trained and evaluated the model, as well as adjusted and optimized it. However, it is important to note that this model is intended for study purposes only and should not be used in real trading.
During the offline learning, we optimize the Agent's policy based on the training sample data. The resulting strategy gives the Agent confidence in its actions. However, such optimism is not always justified and can cause increased risks during the model operation. Today we will look at one of the methods to reduce these risks.
The article considers the theoretical application of quantization in the construction of tree models and showcases the implemented quantization methods in CatBoost. No complex mathematical equations are used.
Data formats used to represent machine learning models play a crucial role in their effectiveness. In recent years, several new types of data have emerged, specifically designed for working with deep learning models. In this article, we will focus on two new data formats that have become widely adopted in modern models.