Examples of passing indicators to a perceptron. The article describes general concepts and showcases the simplest ready-made Expert Advisor followed by the results of its optimization and forward test.
The last two articles were devoted to the Decision Transformer method, which models action sequences in the context of an autoregressive model of desired rewards. In this article, we will look at another optimization algorithm for this method.
Uncover the secrets behind these powerful dimensionality reduction techniques as we dissect their applications within the MQL5 trading environment. Delve into the nuances of Linear Discriminant Analysis (LDA) and Principal Component Analysis (PCA), gaining a profound understanding of their impact on strategy development and market analysis.
In the previous article, we got acquainted with the Decision Transformer. But the complex stochastic environment of the foreign exchange market did not allow us to fully implement the potential of the presented method. In this article, I will introduce an algorithm that is aimed at improving the performance of algorithms in stochastic environments.
Unlock the secrets of MQL5 programming in our latest article! Delve into the essentials of structures, classes, and time functions, empowering your coding journey. Whether you're a beginner or an experienced developer, our guide simplifies complex concepts, providing valuable insights for mastering MQL5. Elevate your programming skills and stay ahead in the world of algorithmic trading!
The article discusses Stochastic Diffusion Search (SDS), which is a very powerful and efficient optimization algorithm based on the principles of random walk. The algorithm allows finding optimal solutions in complex multidimensional spaces, while featuring a high speed of convergence and the ability to avoid local extrema.
We continue to explore reinforcement learning methods. In this article, I will focus on a slightly different algorithm that considers the Agent’s policy in the paradigm of constructing a sequence of actions.
The article considers the algorithm of the MEC family called the simple mind evolutionary computation algorithm (Simple MEC, SMEC). The algorithm is distinguished by the beauty of its idea and ease of implementation.
Number Walls are a variant of Linear Shift Back Registers that prescreen sequences for predictability by checking for convergence. We look at how these ideas could be of use in MQL5.
The article presents a detailed description of the shuffled frog-leaping (SFL) algorithm and its capabilities in solving optimization problems. The SFL algorithm is inspired by the behavior of frogs in their natural environment and offers a new approach to function optimization. The SFL algorithm is an efficient and flexible tool capable of processing a variety of data types and achieving optimal solutions.
AdaBoost, a powerful boosting algorithm designed to elevate the performance of your AI models. AdaBoost, short for Adaptive Boosting, is a sophisticated ensemble learning technique that seamlessly integrates weak learners, enhancing their collective predictive strength.
Explore the fundamentals of MQL5 programming in this beginner-friendly article, where we demystify arrays, custom functions, preprocessors, and event handling, all explained with clarity making every line of code accessible. Join us in unlocking the power of MQL5 with a unique approach that ensures understanding at every step. This article sets the foundation for mastering MQL5, emphasizing the explanation of each line of code, and providing a distinct and enriching learning experience.
The project involves using Python for deep learning-based forecasting in financial markets. We will explore the intricacies of testing the model's performance using key metrics such as Mean Absolute Error (MAE), Mean Squared Error (MSE), and R-squared (R2) and we will learn how to wrap everything into an executable. We will also make a ONNX model file with its EA.
This series of articles introduces several time series labeling methods, which can create data that meets most artificial intelligence models, and targeted data labeling according to needs can make the trained artificial intelligence model more in line with the expected design, improve the accuracy of our model, and even help the model make a qualitative leap!
Here I will consider the fairly new Stochastic Marginal Actor-Critic (SMAC) algorithm, which allows building latent variable policies within the framework of entropy maximization.
Machine Learning is a complex and rewarding field for anyone of any experience. In this article we dive deep into the inner mechanisms powering the models you build, we explore the intricate world of features,predictions and impactful decisions unravelling the complexities and gaining a firm grasp of model interpretation. Learn the art of navigating tradeoffs , enhancing predictions, ranking feature importance all while ensuring robust decision making. This essential read helps you clock more performance from your machine learning models and extract more value for employing machine learning methodologies.
Restrictive Boltzmann Machines are at the basic level, a two-layer neural network that is proficient at unsupervised classification through dimensionality reduction. We take its basic principles and examine if we were to re-design and train it unorthodoxly, we could get a useful signal filter.
Truncated Singular Value Decomposition (SVD) and Non-Negative Matrix Factorization (NMF) are dimensionality reduction techniques. They both play significant roles in shaping data-driven trading strategies. Discover the art of dimensionality reduction, unraveling insights, and optimizing quantitative analyses for an informed approach to navigating the intricacies of financial markets.
Embark on an illuminating journey with Part Two of our MQL5 series. These articles are not just tutorials, they're doorways to an enchanted realm where programming novices and wizards alike unite. What makes this journey truly magical? Part Two of our MQL5 series stands out with its refreshing simplicity, making complex concepts accessible to all. Engage with us interactively as we answer your questions, ensuring an enriching and personalized learning experience. Let's build a community where understanding MQL5 is an adventure for everyone. Welcome to the enchantment!
This series of articles introduces several time series labeling methods, which can create data that meets most artificial intelligence models, and targeted data labeling according to needs can make the trained artificial intelligence model more in line with the expected design, improve the accuracy of our model, and even help the model make a qualitative leap!
Machine learning models are difficult to interpret and understanding why our models deviate from our expectations is critical if we want to gain any value from using such advanced techniques. Without comprehensive insight into the inner workings of our model, we might fail to spot bugs that are corrupting our model's performance, we may waste time over engineering features that aren't predictive and in the long run we risk underutilizing the power of these models. Fortunately, there is a sophisticated and well maintained all in one solution that allows us to see exactly what our model is doing underneath the hood.
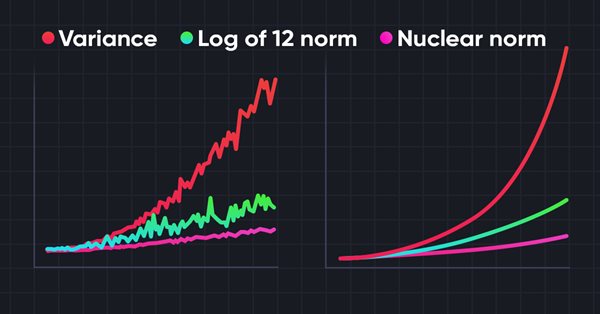
The study of the environment in reinforcement learning is a pressing problem. We have already looked at some approaches previously. In this article, we will have a look at yet another method based on maximizing the nuclear norm. It allows agents to identify environmental states with a high degree of novelty and diversity.
Discover the secrets of algorithmic alchemy as we guide you through the blend of artistry and precision in decoding financial landscapes. Unearth how Random Forests transform data into predictive prowess, offering a unique perspective on navigating the complex terrain of stock markets. Join us on this journey into the heart of financial wizardry, where we demystify the role of Random Forests in shaping market destiny and unlocking the doors to lucrative opportunities
Contrastive training is an unsupervised method of training representation. Its goal is to train a model to highlight similarities and differences in data sets. In this article, we will talk about using contrastive training approaches to explore different Actor skills.
K-Means clustering takes the approach to grouping data points as a process that’s initially focused on the macro view of a data set that uses random generated cluster centroids before zooming in and adjusting these centroids to accurately represent the data set. We will look at this and exploit a few of its use cases.
In this article we explore the application of digital filters on time series represented in the frequency domain so as to extract unique features that may be useful to prediction models.
Dive into the intricate world of decision trees in the latest installment of our Data Science and Machine Learning series. Tailored for traders seeking strategic insights, this article serves as a comprehensive recap, shedding light on the powerful role decision trees play in the analysis of market trends. Explore the roots and branches of these algorithmic trees, unlocking their potential to enhance your trading decisions. Join us for a refreshing perspective on decision trees and discover how they can be your allies in navigating the complexities of financial markets.
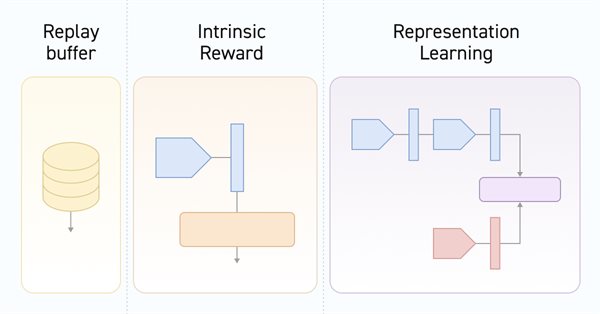
Whenever we consider reinforcement learning methods, we are faced with the issue of efficiently exploring the environment. Solving this issue often leads to complication of the algorithm and training of additional models. In this article, we will look at an alternative approach to solving this problem.
This series of articles introduces several time series labeling methods, which can create data that meets most artificial intelligence models, and targeted data labeling according to needs can make the trained artificial intelligence model more in line with the expected design, improve the accuracy of our model, and even help the model make a qualitative leap!
Perceptrons, single hidden layer networks, can be a good segue for anyone familiar with basic automated trading and is looking to dip into neural networks. We take a step by step look at how this could be realized in a signal class assembly that is part of the MQL5 Wizard classes for expert advisors.
We have already talked more than once about the importance of correctly selecting the reward function, which we use to stimulate the desired behavior of the Agent by adding rewards or penalties for individual actions. But the question remains open about the decryption of our signals by the Agent. In this article, we will talk about reward decomposition in terms of transmitting individual signals to the trained Agent.
Dive into the fascinating realm of algorithmic trading with our beginner-friendly guide to MQL5 programming. Discover the essentials of MQL5, the language powering MetaTrader 5, as we demystify the world of automated trading. From understanding the basics to taking your first steps in coding, this article is your key to unlocking the potential of algorithmic trading even without a programming background. Join us on a journey where simplicity meets sophistication in the exciting universe of MQL5.
As the model is trained based on the experience reproduction buffer, the current Actor policy moves further and further away from the stored examples, which reduces the efficiency of training the model as a whole. In this article, we will look at the algorithm of improving the efficiency of using samples in reinforcement learning algorithms.
We consider XLY, SPDR’s consumer discretionary spending ETF and see if with tools in MetaTrader’s IDE we can sift through an array of data sets in selecting what could work with a forecasting model with a forward outlook of not more than a year.
The last two articles considered the Soft Actor-Critic algorithm, which incorporates entropy regularization into the reward function. This approach balances environmental exploration and model exploitation, but it is only applicable to stochastic models. The current article proposes an alternative approach that is applicable to both stochastic and deterministic models.
In the previous article, we implemented the Soft Actor-Critic algorithm, but were unable to train a profitable model. Here we will optimize the previously created model to obtain the desired results.
XLV is SPDR healthcare ETF and in an age where it is common to be bombarded by a wide array of traditional news items plus social media feeds, it can be pressing to select a data set for use with a model. We try to tackle this problem for this ETF by sizing up some of its critical data sets in MQL5.
Discover the indispensable role of Support Vector Machines (SVM) in shaping the future of trading. This comprehensive guide explores how SVM can elevate your trading strategies, enhance decision-making, and unlock new opportunities in the financial markets. Dive into the world of SVM with real-world applications, step-by-step tutorials, and expert insights. Equip yourself with the essential tool that can help you navigate the complexities of modern trading. Elevate your trading game with SVM—a must-have for every trader's toolbox.
In this article, we will explore the application of regression models from the Scikit-learn package, attempt to convert them into ONNX format, and use the resultant models within MQL5 programs. Additionally, we will compare the accuracy of the original models with their ONNX versions for both float and double precision. Furthermore, we will examine the ONNX representation of regression models, aiming to provide a better understanding of their internal structure and operational principles.
We continue our discussion of reinforcement learning algorithms for solving continuous action space problems. In this article, I will present the Soft Actor-Critic (SAC) algorithm. The main advantage of SAC is the ability to find optimal policies that not only maximize the expected reward, but also have maximum entropy (diversity) of actions.